Weekend Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Questions and Answers by ahad

Page: 9 / 9

Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Overview :

Exam Name: Databricks Certified Associate Developer for Apache Spark 3.5 – Python
Exam Code: Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 136 Q&A's Shared By: ahad
Question 36

44 of 55.

A data engineer is working on a real-time analytics pipeline using Spark Structured Streaming.

They want the system to process incoming data in micro-batches at a fixed interval of 5 seconds.

Which code snippet fulfills this requirement?

Options:

A.

query = df.writeStream \

.outputMode("append") \

.trigger(processingTime="5 seconds") \

.start()

B.

query = df.writeStream \

.outputMode("append") \

.trigger(continuous="5 seconds") \

.start()

C.

query = df.writeStream \

.outputMode("append") \

.trigger(once=True) \

.start()

D.

query = df.writeStream \

.outputMode("append") \

.start()

Discussion
Question 37

3 of 55. A data engineer observes that the upstream streaming source feeds the event table frequently and sends duplicate records. Upon analyzing the current production table, the data engineer found that the time difference in the event_timestamp column of the duplicate records is, at most, 30 minutes.

To remove the duplicates, the engineer adds the code:

df = df.withWatermark("event_timestamp", "30 minutes")

What is the result?

Options:

A.

It removes all duplicates regardless of when they arrive.

B.

It accepts watermarks in seconds and the code results in an error.

C.

It removes duplicates that arrive within the 30-minute window specified by the watermark.

D.

It is not able to handle deduplication in this scenario.

Discussion
Miriam
Highly recommended Dumps. 100% authentic and reliable. Passed my exam with wonderful score.
Milan Aug 14, 2026
I see. Thanks for the information. I'll definitely keep Cramkey in mind for my next exam.
Victoria
Hey, guess what? I passed the certification exam! I couldn't have done it without Cramkey Dumps.
Isabel Aug 17, 2026
Same here! I was so surprised when I saw that almost all the questions on the exam were exactly what I found in their study materials.
Stefan
Thank you so much Cramkey I passed my exam today due to your highly up to date dumps.
Ocean Aug 6, 2026
Agree….Cramkey Dumps are constantly updated based on changes in the exams. They also have a team of experts who regularly review the materials to ensure their accuracy and relevance. This way, you can be sure you're studying the most up-to-date information available.
Rosalie
I passed. I would like to tell all students that they should definitely give Cramkey Dumps a try.
Maja Aug 17, 2026
That sounds great. I'll definitely check them out. Thanks for the suggestion!
Vienna
I highly recommend them. They are offering exact questions that we need to prepare our exam.
Jensen Aug 24, 2026
That's great. I think I'll give Cramkey a try next time I take a certification exam. Thanks for the recommendation!
Question 38

A data engineer is working on the DataFrame:
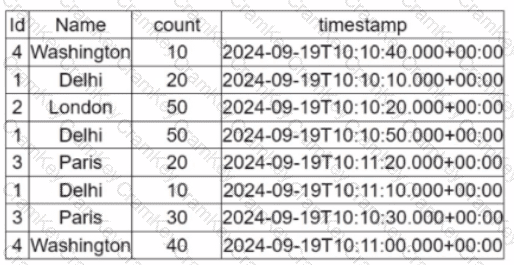
Questions 38

(Referring to the table image: it has columns Id, Name, count, and timestamp.)

Which code fragment should the engineer use to extract the unique values in the Name column into an alphabetically ordered list?

Options:

A.

df.select("Name").orderBy(df["Name"].asc())

B.

df.select("Name").distinct().orderBy(df["Name"])

C.

df.select("Name").distinct()

D.

df.select("Name").distinct().orderBy(df["Name"].desc())

Discussion
Question 39

A data scientist is working with a Spark DataFrame called customerDF that contains customer information. The DataFrame has a column named email with customer email addresses. The data scientist needs to split this column into username and domain parts.

Which code snippet splits the email column into username and domain columns?

Options:

A.

customerDF.select(

col("email").substr(0, 5).alias("username"),

col("email").substr(-5).alias("domain")

)

B.

customerDF.withColumn("username", split(col("email"), "@").getItem(0)) \

.withColumn("domain", split(col("email"), "@").getItem(1))

C.

customerDF.withColumn("username", substring_index(col("email"), "@", 1)) \

.withColumn("domain", substring_index(col("email"), "@", -1))

D.

customerDF.select(

regexp_replace(col("email"), "@", "").alias("username"),

regexp_replace(col("email"), "@", "").alias("domain")

)

Discussion
Page: 9 / 9

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
PDF

$31.5  $104.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Testing Engine

$37.5  $124.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 PDF + Testing Engine

$49.5  $164.99

