Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Questions and Answers by ivan

Page: 7 / 9

Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Overview :

Exam Name: Databricks Certified Associate Developer for Apache Spark 3.5 – Python
Exam Code: Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 136 Q&A's Shared By: ivan
Question 28

A Spark application is experiencing performance issues in client mode because the driver is resource-constrained.

How should this issue be resolved?

Options:

A.

Add more executor instances to the cluster

B.

Increase the driver memory on the client machine

C.

Switch the deployment mode to cluster mode

D.

Switch the deployment mode to local mode

Discussion
Question 29

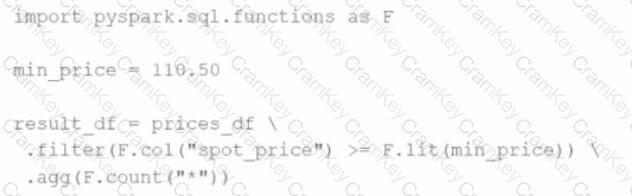
A developer wants to refactor some older Spark code to leverage built-in functions introduced in Spark 3.5.0. The existing code performs array manipulations manually. Which of the following code snippets utilizes new built-in functions in Spark 3.5.0 for array operations?
Questions 29

A)

Questions 29

B)

Questions 29

C)

Questions 29

D)

Questions 29

Options:

A.

result_df = prices_df \

.withColumn("valid_price", F.when(F.col("spot_price") > F.lit(min_price), 1).otherwise(0))

B.

result_df = prices_df \

.agg(F.count_if(F.col("spot_price") >= F.lit(min_price)))

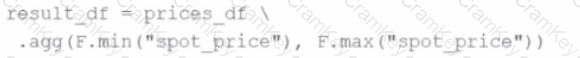
C.

result_df = prices_df \

.agg(F.min("spot_price"), F.max("spot_price"))

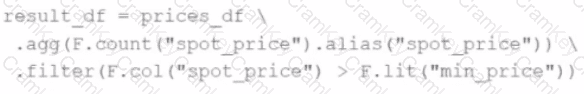
D.

result_df = prices_df \

.agg(F.count("spot_price").alias("spot_price")) \

.filter(F.col("spot_price") > F.lit("min_price"))

Discussion
Question 30

What is the difference between df.cache() and df.persist() in Spark DataFrame?

Options:

A.

Both cache() and persist() can be used to set the default storage level (MEMORY_AND_DISK_SER)

B.

Both functions perform the same operation. The persist() function provides improved performance as its default storage level is DISK_ONLY.

C.

persist() - Persists the DataFrame with the default storage level (MEMORY_AND_DISK_SER) and cache() - Can be used to set different storage levels to persist the contents of the DataFrame.

D.

cache() - Persists the DataFrame with the default storage level (MEMORY_AND_DISK) and persist() - Can be used to set different storage levels to persist the contents of the DataFrame

Discussion
Ella-Rose
Amazing website with excellent Dumps. I passed my exam and secured excellent marks!!!
Alisha Sep 10, 2026
Extremely accurate. They constantly update their materials with the latest exam questions and answers, so you can be confident that what you're studying is up-to-date.
Ernest
That's amazing. I think I'm going to give Cramkey Dumps a try for my next exam. Thanks for telling me about them! CramKey admin please share more questions……You guys are amazing.
Nate Sep 5, 2026
I failed last week, I never know this site , but amazed to see all these questions were in my exam week before. I feel bad now, why I didn’t bother this site. Thanks Cramkey, Excellent Job.
Lennie
I passed my exam and achieved wonderful score, I highly recommend it.
Emelia Sep 25, 2026
I think I'll give Cramkey a try next time I take a certification exam. Thanks for the recommendation!
Syeda
I passed, Thank you Cramkey for your precious Dumps.
Stella Sep 19, 2026
That's great. I think I'll give Cramkey Dumps a try.
Fatima
Hey I passed my exam. The world needs to know about it. I have never seen real exam questions on any other exam preparation resource like I saw on Cramkey Dumps.
Niamh Sep 16, 2026
That's true. Cramkey Dumps are simply the best when it comes to preparing for the certification exam. They have all the key information you need and the questions are very similar to what you'll see on the actual exam.
Question 31

How can a Spark developer ensure optimal resource utilization when running Spark jobs in Local Mode for testing?

Options:

Options:

A.

Configure the application to run in cluster mode instead of local mode.

B.

Increase the number of local threads based on the number of CPU cores.

C.

Use the spark.dynamicAllocation.enabled property to scale resources dynamically.

D.

Set the spark.executor.memory property to a large value.

Discussion
Page: 7 / 9

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
PDF

$31.5  $104.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Testing Engine

$37.5  $124.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 PDF + Testing Engine

$49.5  $164.99