Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Questions and Answers by cassius

Page: 5 / 9

Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Overview :

Exam Name: Databricks Certified Associate Developer for Apache Spark 3.5 – Python
Exam Code: Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 136 Q&A's Shared By: cassius
Question 20

19 of 55.

A Spark developer wants to improve the performance of an existing PySpark UDF that runs a hash function not available in the standard Spark functions library.

The existing UDF code is:

import hashlib

from pyspark.sql.types import StringType

def shake_256(raw):

return hashlib.shake_256(raw.encode()).hexdigest(20)

shake_256_udf = udf(shake_256, StringType())

The developer replaces this UDF with a Pandas UDF for better performance:

@pandas_udf(StringType())

def shake_256(raw: str) -> str:

return hashlib.shake_256(raw.encode()).hexdigest(20)

However, the developer receives this error:

TypeError: Unsupported signature: (raw: str) -> str

What should the signature of the shake_256() function be changed to in order to fix this error?

Options:

A.

def shake_256(raw: str) -> str:

B.

def shake_256(raw: [pd.Series]) -> pd.Series:

C.

def shake_256(raw: pd.Series) -> pd.Series:

D.

def shake_256(raw: [str]) -> [str]:

Discussion
Question 21

34 of 55.

A data engineer is investigating a Spark cluster that is experiencing underutilization during scheduled batch jobs.

After checking the Spark logs, they noticed that tasks are often getting killed due to timeout errors, and there are several warnings about insufficient resources in the logs.

Which action should the engineer take to resolve the underutilization issue?

Options:

A.

Set the spark.network.timeout property to allow tasks more time to complete without being killed.

B.

Increase the executor memory allocation in the Spark configuration.

C.

Reduce the size of the data partitions to improve task scheduling.

D.

Increase the number of executor instances to handle more concurrent tasks.

Discussion
Question 22

A data engineer is building an Apache Spark™ Structured Streaming application to process a stream of JSON events in real time. The engineer wants the application to be fault-tolerant and resume processing from the last successfully processed record in case of a failure. To achieve this, the data engineer decides to implement checkpoints.

Which code snippet should the data engineer use?

Options:

A.

query = streaming_df.writeStream \

.format("console") \

.option("checkpoint", "/path/to/checkpoint") \

.outputMode("append") \

.start()

B.

query = streaming_df.writeStream \

.format("console") \

.outputMode("append") \

.option("checkpointLocation", "/path/to/checkpoint") \

.start()

C.

query = streaming_df.writeStream \

.format("console") \

.outputMode("complete") \

.start()

D.

query = streaming_df.writeStream \

.format("console") \

.outputMode("append") \

.start()

Discussion
Ilyas
Definitely. I felt much more confident and prepared because of the Cramkey Dumps. I was able to answer most of the questions with ease and I think that helped me to score well on the exam.
Saoirse Sep 17, 2026
That's amazing. I'm glad you found something that worked for you. Maybe I should try them out for my next exam.
Atlas
What are these Dumps? Would anybody please explain it to me.
Reign Sep 9, 2026
These are exam dumps for a variety of IT certifications. They have a vast collection of updated questions and answers, which are very helpful in preparing for the exams.
Hendrix
Great website with Great Exam Dumps. Just passed my exam today.
Luka Sep 6, 2026
Absolutely. Cramkey Dumps only provides the latest and most updated exam questions and answers.
Lois
I passed my exam with wonderful score. Their dumps are 100% valid and I felt confident during the exam.
Ernie Sep 1, 2026
Absolutely. The best part is, the answers in the dumps were correct. So, I felt confident and well-prepared for the exam.
Anaya
I found so many of the same questions on the real exam that I had already seen in the Cramkey Dumps. Thank you so much for making exam so easy for me. I passed it successfully!!!
Nina Sep 20, 2026
It's true! I felt so much more confident going into the exam because I had already seen and understood the questions.
Question 23

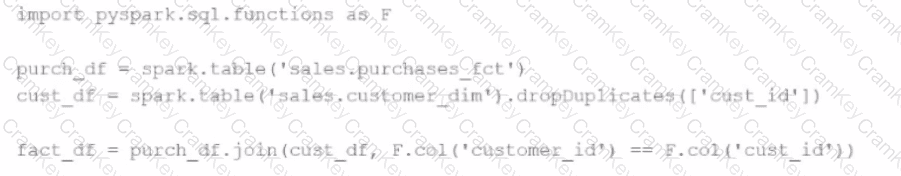
A developer is trying to join two tables, sales.purchases_fct and sales.customer_dim, using the following code:
Questions 23

fact_df = purch_df.join(cust_df, F.col('customer_id') == F.col('custid'))

The developer has discovered that customers in the purchases_fct table that do not exist in the customer_dim table are being dropped from the joined table.

Which change should be made to the code to stop these customer records from being dropped?

Options:

A.

fact_df = purch_df.join(cust_df, F.col('customer_id') == F.col('custid'), 'left')

B.

fact_df = cust_df.join(purch_df, F.col('customer_id') == F.col('custid'))

C.

fact_df = purch_df.join(cust_df, F.col('cust_id') == F.col('customer_id'))

D.

fact_df = purch_df.join(cust_df, F.col('customer_id') == F.col('custid'), 'right_outer')

Discussion
Page: 5 / 9

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
PDF

$31.5  $104.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Testing Engine

$37.5  $124.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 PDF + Testing Engine

$49.5  $164.99

