Weekend Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Questions and Answers by august

Page: 6 / 9

Databricks Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Exam Overview :

Exam Name: Databricks Certified Associate Developer for Apache Spark 3.5 – Python
Exam Code: Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 136 Q&A's Shared By: august
Question 24

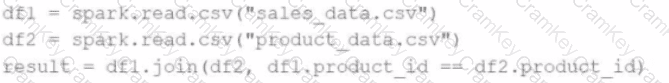
A data engineer writes the following code to join two DataFrames df1 and df2:

df1 = spark.read.csv("sales_data.csv") # ~10 GB

df2 = spark.read.csv("product_data.csv") # ~8 MB

result = df1.join(df2, df1.product_id == df2.product_id)
Questions 24

Which join strategy will Spark use?

Options:

A.

Shuffle join, because AQE is not enabled, and Spark uses a static query plan

B.

Broadcast join, as df2 is smaller than the default broadcast threshold

C.

Shuffle join, as the size difference between df1 and df2 is too large for a broadcast join to work efficiently

D.

Shuffle join because no broadcast hints were provided

Discussion
Question 25

29 of 55.

A Spark application is experiencing performance issues in client mode due to the driver being resource-constrained.

How should this issue be resolved?

Options:

A.

Switch the deployment mode to cluster mode.

B.

Add more executor instances to the cluster.

C.

Increase the driver memory on the client machine.

D.

Switch the deployment mode to local mode.

Discussion
Anaya
I found so many of the same questions on the real exam that I had already seen in the Cramkey Dumps. Thank you so much for making exam so easy for me. I passed it successfully!!!
Nina Aug 5, 2026
It's true! I felt so much more confident going into the exam because I had already seen and understood the questions.
Faye
Yayyyy. I passed my exam. I think all students give these dumps a try.
Emmeline Aug 21, 2026
Definitely! I have no doubt new students will find them to be just as helpful as I did.
Carson
Yeah, definitely. I would definitely recommend Cramkey Dumps to anyone who is preparing for an exam.
Rufus Aug 7, 2026
Me too. They're a lifesaver!
Elise
I've heard that Cramkey is one of the best websites for exam dumps. They have a high passing rate and the questions are always up-to-date. Is it true?
Cian Aug 10, 2026
Definitely. The dumps are constantly updated to reflect the latest changes in the certification exams. And I also appreciate how they provide explanations for the answers, so I could understand the reasoning behind each question.
Question 26

25 of 55.

A Data Analyst is working on employees_df and needs to add a new column where a 10% tax is calculated on the salary.

Additionally, the DataFrame contains the column age, which is not needed.

Which code fragment adds the tax column and removes the age column?

Options:

A.

employees_df = employees_df.withColumn("tax", col("salary") * 0.1).drop("age")

B.

employees_df = employees_df.withColumn("tax", lit(0.1)).drop("age")

C.

employees_df = employees_df.dropField("age").withColumn("tax", col("salary") * 0.1)

D.

employees_df = employees_df.withColumn("tax", col("salary") + 0.1).drop("age")

Discussion
Question 27

A developer is working with a pandas DataFrame containing user behavior data from a web application.

Which approach should be used for executing a groupBy operation in parallel across all workers in Apache Spark 3.5?

A)

Use the applylnPandas API

B)
Questions 27

C)

Questions 27

D)

Questions 27

Options:

A.

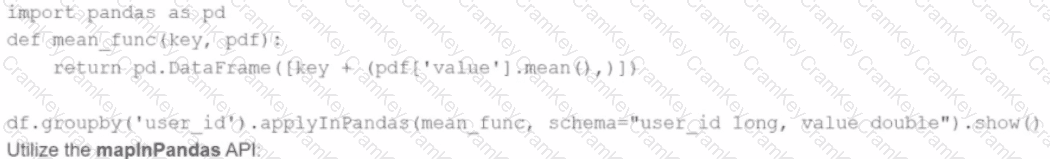
Use the applyInPandas API:

df.groupby("user_id").applyInPandas(mean_func, schema="user_id long, value double").show()

B.

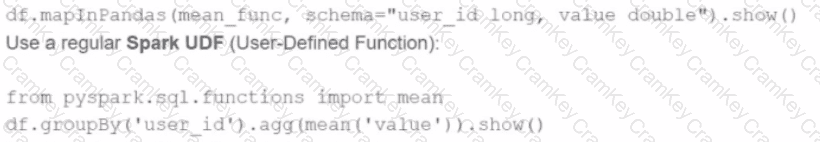
Use the mapInPandas API:

df.mapInPandas(mean_func, schema="user_id long, value double").show()

C.

Use a regular Spark UDF:

from pyspark.sql.functions import mean

df.groupBy("user_id").agg(mean("value")).show()

D.

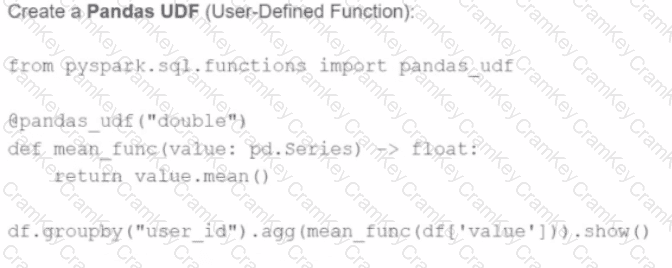
Use a Pandas UDF:

@pandas_udf("double")

def mean_func(value: pd.Series) -> float:

return value.mean()

df.groupby("user_id").agg(mean_func(df["value"])).show()

Discussion
Page: 6 / 9

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5
PDF

$31.5  $104.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 Testing Engine

$37.5  $124.99

Databricks-Certified-Associate-Developer-for-Apache-Spark-3.5 PDF + Testing Engine

$49.5  $164.99