Pre-Winter Sale Limited Time 65% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: get65

Databricks Updated Databricks-Certified-Professional-Data-Engineer Exam Questions and Answers by cohen

Page: 14 / 14

Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview :

Exam Name: Databricks Certified Data Engineer Professional Exam
Exam Code: Databricks-Certified-Professional-Data-Engineer Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 202 Q&A's Shared By: cohen
Question 56

Which distribution does Databricks support for installing custom Python code packages?

Options:

A.

sbt

B.

CRAN

C.

CRAM

D.

nom

E.

Wheels

F.

jars

Discussion
Question 57

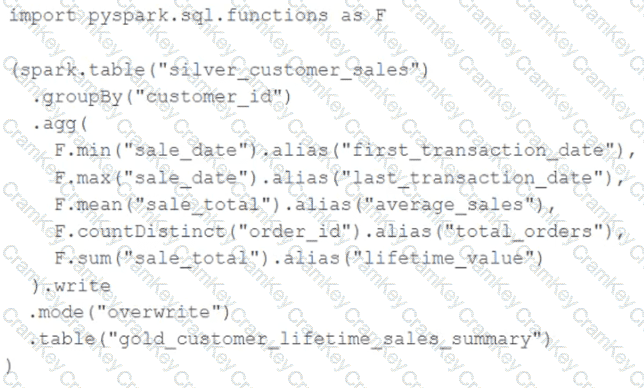
The data engineering team maintains the following code:
Questions 57

Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?

Options:

A.

The silver_customer_sales table will be overwritten by aggregated values calculated from all records in the gold_customer_lifetime_sales_summary table as a batch job.

B.

A batch job will update the gold_customer_lifetime_sales_summary table, replacing only those rows that have different values than the current version of the table, using customer_id as the primary key.

C.

The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job.

D.

An incremental job will leverage running information in the state store to update aggregate values in the gold_customer_lifetime_sales_summary table.

E.

An incremental job will detect if new rows have been written to the silver_customer_sales table; if new rows are detected, all aggregates will be recalculated and used to overwrite the gold_customer_lifetime_sales_summary table.

Discussion
Andrew
Are these dumps helpful?
Jeremiah Sep 19, 2026
Yes, Don’t worry!!! I'm confident you'll find them to be just as helpful as I did. Good luck with your exam!
Erik
Hey, I have passed my exam using Cramkey Dumps?
Freyja Sep 15, 2026
Really, what are they? All come in your pool? Please give me more details, I am going to have access their subscription. Please brother, give me more details.
Madeleine
Passed my exam with my dream score…. Guys do give these dumps a try. They are authentic.
Ziggy Sep 26, 2026
That's really impressive. I think I might give Cramkey Dumps a try for my next certification exam.
Marley
Hey, I heard the good news. I passed the certification exam!
Jaxson Aug 31, 2026
Yes, I passed too! And I have to say, I couldn't have done it without Cramkey Dumps.
Question 58

A Structured Streaming job deployed to production has been resulting in higher than expected cloud storage costs. At present, during normal execution, each micro-batch of data is processed in less than 3 seconds; at least 12 times per minute, a micro-batch is processed that contains 0 records. The streaming write was configured using the default trigger settings. The production job is currently scheduled alongside many other Databricks jobs in a workspace with instance pools provisioned to reduce start-up time for jobs with batch execution. Holding all other variables constant and assuming records need to be processed in less than 10 minutes, which adjustment will meet the requirement?

Options:

A.

Set the trigger interval to 500 milliseconds; setting a small but non-zero trigger interval ensures that the source is not queried too frequently.

B.

Set the trigger interval to 3 seconds; the default trigger interval is consuming too many records per batch, resulting in spill to disk that can increase volume costs.

C.

Set the trigger interval to 10 minutes; each batch calls APIs in the source storage account, so decreasing trigger frequency to the maximum allowable threshold should minimize this cost.

D.

Use the trigger once option and configure a Databricks job to execute the query every 10 minutes; this approach minimizes costs for both compute and storage.

Discussion
Question 59

The DevOps team has configured a production workload as a collection of notebooks scheduled to run daily using the Jobs Ul. A new data engineering hire is onboarding to the team and has requested access to one of these notebooks to review the production logic.

What are the maximum notebook permissions that can be granted to the user without allowing accidental changes to production code or data?

Options:

A.

Can manage

B.

Can edit

C.

Can run

D.

Can Read

Discussion
Page: 14 / 14
Title
Questions
Posted

Databricks-Certified-Professional-Data-Engineer
PDF

$36.75  $104.99

Databricks-Certified-Professional-Data-Engineer Testing Engine

$43.75  $124.99

Databricks-Certified-Professional-Data-Engineer PDF + Testing Engine

$57.75  $164.99

