Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Professional-Data-Engineer Exam Questions and Answers by humaira

Page: 13 / 14

Databricks Databricks-Certified-Professional-Data-Engineer Exam Overview :

Exam Name: Databricks Certified Data Engineer Professional Exam
Exam Code: Databricks-Certified-Professional-Data-Engineer Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 202 Q&A's Shared By: humaira
Question 52

An analytics team wants to run a short-term experiment in Databricks SQL on the customer transactions Delta table (about 20 billion records) created by the data engineering team. Which strategy should the data engineering team use to ensure minimal downtime and no impact on the ongoing ETL processes?

Options:

A.

Create a new table for the analytics team using a CTAS statement.

B.

Deep clone the table for the analytics team.

C.

Give the analytics team direct access to the production table.

D.

Shallow clone the table for the analytics team.

Discussion
Question 53

A DLT pipeline includes the following streaming tables:

Raw_lot ingest raw device measurement data from a heart rate tracking device.

Bgm_stats incrementally computes user statistics based on BPM measurements from raw_lot.

How can the data engineer configure this pipeline to be able to retain manually deleted or updated records in the raw_iot table while recomputing the downstream table when a pipeline update is run?

Options:

A.

Set the skipChangeCommits flag to true on bpm_stats

B.

Set the SkipChangeCommits flag to true raw_lot

C.

Set the pipelines, reset, allowed property to false on bpm_stats

D.

Set the pipelines, reset, allowed property to false on raw_iot

Discussion
Rae
I tried using Cramkey dumps for my recent certification exam and I found them to be more accurate and up-to-date compared to other dumps I've seen. Passed the exam with wonderful score.
Rayyan Sep 16, 2026
I see your point. Thanks for sharing your thoughts. I might give it a try for my next certification exam.
Elise
I've heard that Cramkey is one of the best websites for exam dumps. They have a high passing rate and the questions are always up-to-date. Is it true?
Cian Sep 26, 2026
Definitely. The dumps are constantly updated to reflect the latest changes in the certification exams. And I also appreciate how they provide explanations for the answers, so I could understand the reasoning behind each question.
Aliza
I used these dumps for my recent certification exam and I can say with certainty that they're absolutely valid dumps. The questions were very similar to what came up in the actual exam.
Jakub Sep 12, 2026
That's great to hear. I am going to try them soon.
Esmae
I highly recommend Cramkey Dumps to anyone preparing for the certification exam.
Mollie Sep 15, 2026
Absolutely. They really make it easier to study and retain all the important information. I'm so glad I found Cramkey Dumps.
Question 54

The Databricks CLI is use to trigger a run of an existing job by passing the job_id parameter. The response that the job run request has been submitted successfully includes a filed run_id.

Which statement describes what the number alongside this field represents?

Options:

A.

The job_id is returned in this field.

B.

The job_id and number of times the job has been are concatenated and returned.

C.

The number of times the job definition has been run in the workspace.

D.

The globally unique ID of the newly triggered run.

Discussion
Question 55

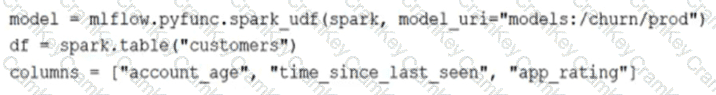
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.

The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.
Questions 55

Which code block will output DataFrame with the schema ' ' customer_id LONG, predictions DOUBLE ' ' ?

Options:

A.

Model, predict (df, columns)

B.

Df, map (lambda k:midel (x [columns]) ,select ( ' ' customer_id predictions ' ' )

C.

Df. Select ( ' ' customer_id ' ' .

Model ( ' ' columns) alias ( ' ' predictions ' ' )

D.

Df.apply(model, columns). Select ( ' ' customer_id, prediction ' '

Discussion
Page: 13 / 14
Title
Questions
Posted

Databricks-Certified-Professional-Data-Engineer
PDF

$31.5  $104.99

Databricks-Certified-Professional-Data-Engineer Testing Engine

$37.5  $124.99

Databricks-Certified-Professional-Data-Engineer PDF + Testing Engine

$49.5  $164.99

