Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Data-Engineer-Associate Exam Questions and Answers by justin

Page: 4 / 17

Databricks Databricks-Certified-Data-Engineer-Associate Exam Overview :

Exam Name: Databricks Certified Data Engineer Associate Exam
Exam Code: Databricks-Certified-Data-Engineer-Associate Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 230 Q&A's Shared By: justin
Question 16

A data engineer needs to create a table in Databricks using data from a CSV file at location /path/to/csv.

They run the following command:
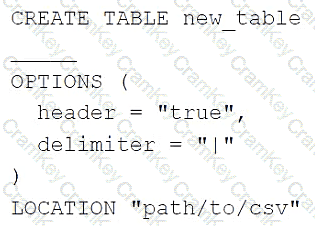
Questions 16

Which of the following lines of code fills in the above blank to successfully complete the task?

Options:

A.

None of these lines of code are needed to successfully complete the task

B.

USING CSV

C.

FROM CSV

D.

USING DELTA

E.

FROM " path/to/csv "

Discussion
Madeleine
Passed my exam with my dream score…. Guys do give these dumps a try. They are authentic.
Ziggy Sep 26, 2026
That's really impressive. I think I might give Cramkey Dumps a try for my next certification exam.
Anaya
I found so many of the same questions on the real exam that I had already seen in the Cramkey Dumps. Thank you so much for making exam so easy for me. I passed it successfully!!!
Nina Sep 20, 2026
It's true! I felt so much more confident going into the exam because I had already seen and understood the questions.
Sam
Can I get help from these dumps and their support team for preparing my exam?
Audrey Sep 25, 2026
Definitely, you won't regret it. They've helped so many people pass their exams and I'm sure they'll help you too. Good luck with your studies!
Honey
I highly recommend it. They made a big difference for me and I'm sure they'll help you too. Just make sure to use them wisely and not solely rely on them. They should be used as a supplement to your regular studies.
Antoni Sep 12, 2026
Good point. Thanks for the advice. I'll definitely keep that in mind.
Question 17

A data engineer has three tables in a Delta Live Tables (DLT) pipeline. They have configured the pipeline to drop invalid records at each table. They notice that some data is being dropped due to quality concerns at some point in the DLT pipeline. They would like to determine at which table in their pipeline the data is being dropped.

Which of the following approaches can the data engineer take to identify the table that is dropping the records?

Options:

A.

They can set up separate expectations for each table when developing their DLT pipeline.

B.

They cannot determine which table is dropping the records.

C.

They can set up DLT to notify them via email when records are dropped.

D.

They can navigate to the DLT pipeline page, click on each table, and view the data quality statistics.

E.

They can navigate to the DLT pipeline page, click on the “Error” button, and review the present errors.

Discussion
Question 18

A data engineering team needs to ingest historical CSV files from a cloud-storage location that already contains 50,000 existing files. The team also expects new files to arrive continuously. The team wants to use Auto Loader to incrementally process both the existing files and new arrivals efficiently.

Which Auto Loader mode should the team configure for this use case?

Options:

A.

Use file notification mode because it scales efficiently for both large numbers of existing files and continuous new arrivals by using cloud-storage events rather than repeatedly listing directories.

B.

Use directory listing mode because it provides better performance for the initial processing of 50,000 existing files through optimized incremental listing capabilities.

C.

Use directory listing mode initially to process the 50,000 existing files, and then reconfigure the stream to use file notification mode for ongoing ingestion of new arrivals.

D.

Use file notification mode only after all existing files have been processed because it cannot efficiently handle large volumes of pre-existing files.

Discussion
Question 19

Which tool is used by Auto Loader to process data incrementally?

Options:

A.

Spark Structured Streaming

B.

Unity Catalog

C.

Checkpointing

D.

Databricks SQL

Discussion
Page: 4 / 17
Title
Questions
Posted

Databricks-Certified-Data-Engineer-Associate
PDF

$31.5  $104.99

Databricks-Certified-Data-Engineer-Associate Testing Engine

$37.5  $124.99

Databricks-Certified-Data-Engineer-Associate PDF + Testing Engine

$49.5  $164.99

