Halloween Sale Limited Time 70% Discount Offer - Ends in 0d 00h 00m 00s - Coupon code: cram70off

Databricks Updated Databricks-Certified-Data-Engineer-Associate Exam Questions and Answers by marco

Page: 12 / 17

Databricks Databricks-Certified-Data-Engineer-Associate Exam Overview :

Exam Name: Databricks Certified Data Engineer Associate Exam
Exam Code: Databricks-Certified-Data-Engineer-Associate Dumps
Vendor: Databricks Certification: Databricks Certification
Questions: 230 Q&A's Shared By: marco
Question 48

A data engineer is designing a cost-optimized, event-driven pipeline. They configure a Lakeflow Job with a File Arrival trigger to watch an Amazon S3 bucket. The job runs a notebook that uses Auto Loader with trigger(availableNow=True) to ingest data into a Bronze table.

What is the technical relationship between the File Arrival trigger and Auto Loader in this integration pattern?

Options:

A.

The File Arrival trigger starts the job run, while Auto Loader uses its internal checkpoint to independently identify and process only the new files that have arrived since the last successful commit.

B.

Auto Loader must be configured in File Notification mode to work with a Lakeflow Job File Arrival trigger.

C.

Using a File Arrival trigger requires the engineer to disable Auto Loader checkpointing to prevent the job from processing the same file multiple times.

D.

The File Arrival trigger automatically passes the specific file path of the new arrival to Auto Loader, allowing the engineer to omit the source-path configuration from the code.

Discussion
Stefan
Thank you so much Cramkey I passed my exam today due to your highly up to date dumps.
Ocean Sep 8, 2026
Agree….Cramkey Dumps are constantly updated based on changes in the exams. They also have a team of experts who regularly review the materials to ensure their accuracy and relevance. This way, you can be sure you're studying the most up-to-date information available.
River
Hey, I used Cramkey Dumps to prepare for my recent exam and I passed it.
Lewis Sep 10, 2026
Yeah, I used these dumps too. And I have to say, I was really impressed with the results.
Yusra
I passed my exam. Cramkey Dumps provides detailed explanations for each question and answer, so you can understand the concepts better.
Alisha Sep 11, 2026
I recently used their dumps for the certification exam I took and I have to say, I was really impressed.
Lennox
Something Special that they provide a comprehensive overview of the exam content. They cover all the important topics and concepts, so you can be confident that you are well-prepared for the test.
Aiza Sep 2, 2026
That makes sense. What makes Cramkey Dumps different from other study materials?
Question 49

A data engineer needs to apply custom logic to identify employees with more than 5 years of experience in array column employees in table stores. The custom logic should create a new column exp_employees that is an array of all of the employees with more than 5 years of experience for each row. In order to apply this custom logic at scale, the data engineer wants to use the FILTER higher-order function.

Which of the following code blocks successfully completes this task?
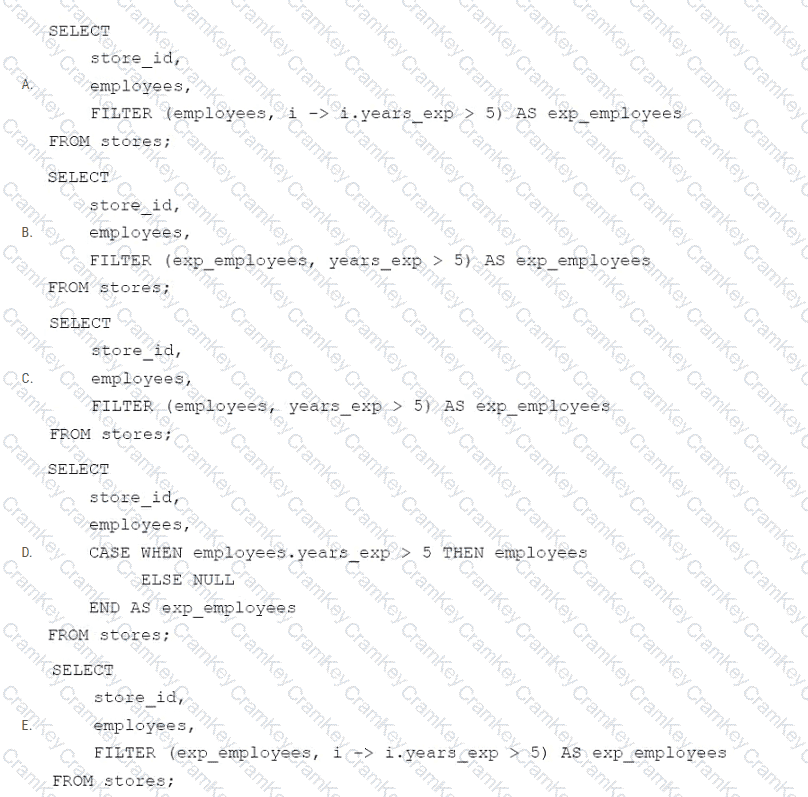
Questions 49

Options:

A.

Option A

B.

Option B

C.

Option C

D.

Option D

E.

Option E

Discussion
Question 50

A data engineer is troubleshooting two different pipeline failures:

    Pipeline A fails with a java.lang.OutOfMemoryError immediately after display(df.collect()) is called on a 100 GB dataset.

    Pipeline B fails during a wide transformation joining two large tables, with an ExecutorLostFailure message indicating executor-memory exhaustion during the shuffle.

Which action should the data engineer take to address these two issues?

Options:

A.

For Pipeline A, switch to a storage-optimized cluster; for Pipeline B, use a compute-optimized cluster.

B.

For both pipelines, enable Adaptive Query Execution because it automatically manages all driver and executor memory allocation.

C.

For Pipeline A, increase the number of executors; for Pipeline B, increase driver memory.

D.

For Pipeline A, address driver memory by removing the full collect() or increasing driver capacity; for Pipeline B, increase shuffle partitions or executor memory.

Discussion
Question 51

A data engineer needs to ingest JSON change data from Salesforce into Unity Catalog-governed Delta tables using a low-code, fully managed experience.

Which Databricks capability should the data engineer use?

Options:

A.

A Lakeflow Connect managed Salesforce connector that writes to Unity Catalog Delta tables.

B.

The Salesforce REST API in a PySpark notebook to query changed records and write them to Delta tables.

C.

Auto Loader with a file-arrival trigger monitoring DBFS.

D.

Auto Loader reading JSON files from an Amazon S3 bucket populated by a separate Salesforce export process.

Discussion
Page: 12 / 17
Title
Questions
Posted

Databricks-Certified-Data-Engineer-Associate
PDF

$31.5  $104.99

Databricks-Certified-Data-Engineer-Associate Testing Engine

$37.5  $124.99

Databricks-Certified-Data-Engineer-Associate PDF + Testing Engine

$49.5  $164.99

